
Insurance data modernization is the process of replacing fragmented data infrastructure with connected, governed systems that make insurance data easier to access, analyse, and use. It matters because underwriting, claims, pricing, finance, regulatory reporting, and customer service all depend on accurate data moving quickly between systems.
According to recent research, 74% of insurers still depend on outdated legacy systems for essential functions like pricing, rating, and underwriting.
At Vidi Corp, our data modernization services experts build cloud databases, API integrations, automated data pipelines, and business intelligence systems for financial services and other data-intensive organisations. Our projects often involve consolidating disconnected systems through a structured data analytics implementation process and turning their data into continuously refreshed reporting and analytics.
In this guide, we explain what insurance data modernization involves, why legacy insurance systems create problems, what a modern insurance data architecture looks like, and how to implement modernization in phases. We will also cover practical use cases, measurable benefits, common challenges, and the KPIs insurers can use to track progress.
Insurance data modernization is the redesign of how an insurer collects, integrates, stores, governs, processes, and analyses its data. The objective is to create a reliable data foundation that can support operational reporting, advanced analytics, automation, and AI.
This normally means connecting data from systems such as:
Insurance makes data modernization particularly complex because carriers can hold decades of historical policy and claims information. They also work with regulated data, complex actuarial models, third-party data, and large volumes of unstructured documents. For larger organisations, this often forms part of a broader enterprise data analytics strategy that standardises how information is managed across departments.
A modernized environment does not necessarily require replacing every core insurance application. Existing systems can remain operational while APIs, automated pipelines, cloud storage, governance controls, and analytical layers make their data easier to use.
Data modernization creates a common analytical environment for information from policy, claims, finance, CRM, and other systems. APIs and automated pipelines move the relevant records into governed data models, so departments can use the same definitions instead of independently consolidating extracts.
Vidi Corp implemented a centralised real-time data environment for financial services company TGUC Financial. The project reduced data silos from six systems to one centralised database and cut manual data consolidation by 95%.
Automated pipelines allow operational and management reporting to refresh whenever the underlying data changes or according to a defined schedule. This gives underwriters, claims teams, finance leaders, and executives access to current information without waiting for another reporting cycle. Leadership teams can also use Power BI executive dashboards to monitor the most important insurance KPIs from one high-level view.”
For the same TGUC Financial project, Vidi Corp reduced report generation time from 48 hours to under five minutes. The client also reported a 40% faster turnaround on strategic decisions and two fewer business days per week spent on executive review cycles.
Modernization automates repetitive extraction, transformation, refresh, and distribution processes. Teams can then spend more time interpreting claims, risk, financial, and customer performance instead of preparing the underlying dataset. Insurers can extend this further with Power Automate workflows that trigger report distribution, approvals, notifications, document processing, and other actions when data changes
Vidi Corp automated Power BI reporting for a financial services business using data from QuickBooks Online, Zoho CRM, Zoho Creator, and Excel. The client reported that the automated reporting saved more than 10 hours every month.
Automated integrations apply the same extraction and transformation logic on every refresh. Validation rules, central definitions, and API feeds also reduce opportunities for errors to enter during repeated copying, reformatting, and reconciliation.
Vidi Corp built a cloud RDBMS, REST API integrations, and real-time Power BI reporting for War Room Operations. The client reported an 80% reduction in data-entry errors and data integrity of 99.7% after implementation.
Modernized insurance data can connect financial, sales, operational, and customer information in the same analytical environment. Executives can then drill into the drivers behind cost, revenue, retention, loss, or portfolio performance and act on specific opportunities.
Vidi Corp developed automated Power BI reporting across finance, sales, procurement, marketing, and operations for Neterra. One report identified an immediate €50,000 cost-saving opportunity, while the analysis also uncovered opportunities worth €10,000–€20,000 in monthly recurring revenue.
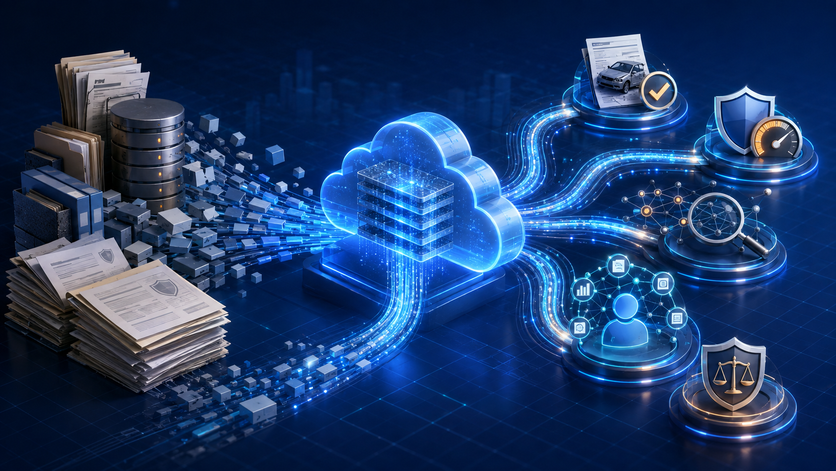
Data modernization can sound abstract until you see what the work consists of. These are the four builds we deliver most often for insurers, with the actual tools named.
This is for carriers whose policy, claims, or finance data still sits in on-premise SQL Server databases, ageing warehouses, or systems approaching end of support. The data works, but it is invisible to modern analytics tools and expensive to keep alive.
Our Microsoft Fabrics consultants migrate these stores into Microsoft Fabric, with OneLake as the unified lakehouse. Source tables from policy admin, claims, and billing systems are mapped, validated against trusted totals, and landed in governed Fabric workspaces where lineage, access controls, and sensitivity labels come as part of the platform.
The business impact is that decades of historical policy and claims data become available to every downstream tool from one governed location. Reporting, actuarial analysis, and AI workloads draw from the same lakehouse, and the legacy store can be retired once dependent processes are re-pointed.
The benefit is a faster, lighter reporting foundation that the carrier controls:
Decades of historical policy and claims data become available from one governed location, and the legacy store can be retired once dependent processes are re-pointed.
This is for insurers whose reporting depends on someone manually exporting from telephony, policy, claims, and CRM systems every week and stitching the results together in spreadsheets.
Our Power BI consultants build scheduled pipelines that extract from each source automatically and feed Power BI insurance reporting, call volumes and handling KPIs from telephony, premium and renewal figures from policy admin, claims frequency and severity from the claims platform, and pipeline data from the CRM, refreshed on schedule into one set of dashboards.
The benefit is that reporting stops being a weekly assembly job and becomes something the team reads rather than builds. Figures stay consistent across departments because every dashboard draws from the same governed extraction, not from whichever export an analyst last saved. Analysts spend their time interpreting the numbers instead of collecting them.
This is for insurance operations teams drowning in document routing and spreadsheet-based tools: claims documents forwarded by email, underwriting files chased manually, and departmental trackers maintained by hand.
Our Power Automate consultants implements Power Automate flows that route claims and underwriting documents to the right handler with approvals, notifications, and status tracking built in, and replaces spreadsheet tools with Power Apps that write directly to governed data instead of local files.
The impact shows up in how work moves: documents follow a defined, auditable path rather than an inbox trail, handlers spend their time on decisions instead of chasing, and the data these processes generate lands in the same governed environment as everything else.
This is for insurers holding policy documents, compliance records, and claims correspondence across shared drives and local folders, with no consistent retention or access control.
Vidi Corp structures these into SharePoint for ISO 27001 compliance with enforced metadata, retention policies matched to record-keeping requirements, and access controls aligned to who actually needs each document class. Retention and deletion happen by rule rather than by memory.
The impact is a compliance position as much as a convenience: when a regulator, auditor, or claimant requests records, the documents are findable, access is provable, and nothing is retained longer than the rules allow.
A US-based property and casualty insurance carrier ran its phone system and internal meetings on Zoom. All of that communications data lived inside Zoom, cut off from any reporting layer. The team wanted it in their own environment, refreshed on a schedule, without anyone exporting files by hand.
This is data modernization in its most practical form. A manual, siloed source becomes an automated pipeline that the business owns and controls.
Vidi Corp deployed its cloud-based Zoom connector to pull the carrier’s phone and meeting data automatically. The connector maps 21 to 24 Zoom API endpoints into a structured set of database tables. It runs on our side once authenticated, so the carrier installed no software of their own.
We customized the pipeline to write directly into the carrier’s own PostgreSQL database, hosted on their infrastructure. No data is stored in any Vidi-owned system, including logs.
Data moves into the database over an authenticated connection that we configured and documented during onboarding.
We applied AES-256 encryption so customer data is stored as ciphertext rather than readable text. Names and other personal details sit in the database as encrypted strings.
Decryption runs only through the ODBC connector we configured, which holds the encryption key. Anyone who reaches the database without that connector sees encrypted values, even with a valid database login. Database credentials alone are not enough to expose customer information.
For insurers, encrypting personal data at rest supports data security obligations such as the GLBA Safeguards Rule and the NAIC Insurance Data Security Model Law.
We delivered a Zoom analytics dashboard that models the extracted calls and meetings data for automated reporting.
The carrier’s phone and meeting data now lands in their own database on a schedule and feeds Power BI directly. Reporting draws from one current source that the carrier owns outright. Nobody assembles a report from manual exports anymore.
Because this is insurance data, the design put governance first. The engagement ran through the carrier’s enterprise architecture review board and an NDA before any data moved.
The architecture keeps the carrier in full control at every step. Their database, their infrastructure, and no vendor-side retention of their data. For an insurer weighing data residency and disclosure obligations, that control is the point rather than an afterthought.
Data modernization is only worth doing if it changes how the business runs. Here is what a connected, governed data foundation changes across the insurance workflows it touches most.
Without a shared data foundation, underwriting relies on policy, claims, and external data that someone pulls together by hand for each case. The picture is partial and slow to build.
Modernization lands historical policies, claims, risk attributes, and third-party datasets in one governed model, so underwriters see the full risk picture without assembling it. Turnaround shortens, and decisions like risk scoring and pricing stay consistent from one underwriter to the next. Clean, current data also gives predictive models something reliable to score against, and metrics such as loss ratio by risk segment or quote-to-bind rate come from one agreed source.
Claims data is normally split across first notice of loss, policy details, payments, reserves, adjuster notes, and documents. While it stays split, cost and status are hard to see until well after the fact.
Modernization connects those sources, so claim frequency, severity, cycle time, and adjuster workload are visible as claims move rather than weeks later. Document AI can read claim forms, invoices, and inspection reports, so routine cases progress automatically while complex ones are routed for review. Straightforward claims settle faster, and adjusters spend their time where judgement is actually needed.
When claim data sits in isolation, every claim tends to get the same review, and the signals that only appear across combined data stay hidden.
Joining claim information to customer history, payments, addresses, devices, and prior investigations lets models score risk and flag unusual patterns. Investigators then prioritize the cases that warrant scrutiny instead of treating every claim alike. The change shows up as less leakage and less time spent on clean claims.
A single policyholder may hold several products and deal with brokers, call centres, billing, and claims teams separately. No one team sees the whole relationship.
A customer 360 model brings those interactions into one view, so retention, cross-sell, service history, and lifetime value can be read per customer. Renewal and cross-sell decisions then rest on the full relationship rather than one system’s slice of it.
When each reporting period rebuilds the same figure in a slightly different way, numbers drift and proving how they were derived is slow. Automated financial reporting becomes possible with insurance data modernization.
Modernization creates governed datasets for finance, actuarial, solvency, and regulatory reporting, so a metric is produced the same way every period. Data lineage shows which source records and transformations feed a submitted figure, which shortens audit and review cycles.
Actuarial work often starts with locating and cleaning long histories of premiums, claims, exposures, and reserves before any modelling can begin.
Centralizing and standardizing those histories moves that time into the work that matters: scenario modelling, portfolio analysis, loss forecasting, and pricing research. The data foundation, not the spreadsheet prep, becomes the starting point.
Distribution is often judged on volume alone, because the data needed to see profitability is scattered across systems.
Combining broker, quote, policy, premium, and claims data shows written premium, bind rate, loss ratio, and renewal rate by partner in one place. Commercial teams can then tell high-volume partners apart from the ones writing genuinely profitable business.
Data modernization works best as a sequence, not a single project. Each step lowers risk and keeps the business in control of its own data. The approach below applies whatever tools you use.
Start by listing where insurance data actually lives. For most carriers that means policy administration, claims, billing, CRM, telephony, and spreadsheets held by individual teams. Assign an owner to each source before anything moves.
This map is the foundation for everything that follows. It shows which systems hold nonpublic personal information. It also shows where the same data is duplicated and where it drifts out of sync.
Insurance data carries specific legal duties, so map them before you design anything. The main obligations for US carriers are:
One point matters for multi-state carriers. You effectively have to meet the strictest rule you are exposed to. So New York’s standard often sets the bar in practice.
Decide where the data will live and who holds it. Many carriers keep the database on their own infrastructure to satisfy data-residency and disclosure requirements. Confirm in writing that no vendor keeps copies of the data, including inside logs.
Control of the data is a compliance position, not just a technical preference. It is far easier to prove how nonpublic information is handled when it never leaves your environment.
Every obligation above points to a control you can build in. This is where data modernization does the compliance work:
The point is to design controls against named requirements, not to add security features at random. Each control should trace back to a rule.
Replace manual exports with scheduled pipelines that move data into your chosen environment. Reporting then draws from one current source instead of many copies. Figures stay consistent, and the manual work behind each report disappears.
Regulations move. The NAIC is updating its model law in 2026 with new provisions on artificial intelligence and third-party data. Design the pipeline so new sources, fields, and controls can be added later without a rebuild.
This is the sequence we follow when we modernise data for insurers. We keep the data in the client’s own environment, map each control to the regulations that apply, and automate the flow into reporting. The case study above shows how that worked for a US carrier.
Insurance data modernization is not simply a database migration. It is the process of building a reliable flow from source systems to governed data, analytics, automation, and operational decisions.
The strongest projects start with one measurable insurance problem and expand once the underlying data architecture has proven itself. If you need support defining the architecture and roadmap, our data strategy consulting services cover data architecture, governance, technology selection, and implementation planning. Contact Vidi Corp to discuss the approach.
Insurance data modernization is the process of redesigning how policy, claims, financial, customer, and risk data is integrated, stored, governed, and analysed. It usually involves automated data pipelines, cloud platforms, central data models, governance controls, and analytics.
It allows insurers to access more reliable and current information across disconnected systems. This supports faster reporting, underwriting analytics, claims automation, fraud detection, regulatory reporting, customer analytics, and AI.
No. Modernization can connect existing systems to a modern analytical platform through APIs, database integrations, files, or custom pipelines.
Core applications can then be replaced gradually if there is a business case for doing so.
An insurance data platform is the infrastructure used to collect, store, transform, govern, and distribute insurance data.
It can include a data lake, warehouse or lakehouse, ETL pipelines, APIs, data models, governance systems, and analytics tools.


